EMBEDDED LANGUAGE PODS
Embed language experts into your product team. Launch faster without scattered specialists.
Our services
Language breaks during mid-build. We fix it before that.
Add copy late, and your product or website project could launch with the wrong messaging. We define language early, so rework won’t slow you down mid-build.
UX & Microcopy Implementation
Clear UX copy and microcopy across screens, states, and key interaction points. Users know what to do next without hesitation, and teams stop patching clarity issues later.
ContentOps Management
Structured content operations across launches, updates, and active product work. Requests move faster without constant follow-ups, re-briefs, or bottlenecks.
Product Language Ownership
Consistent product language across flows, features, and releases. Teams stop rewriting the same decisions in different places.
AI & Conversational Design Management
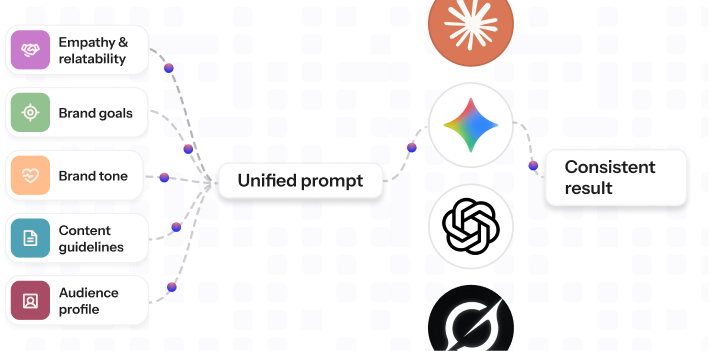
Clear prompts, responses, and conversation flows across AI experiences. Interactions stay usable, consistent, and easier to scale.
GTM & Product Alignment
Aligned language across product, campaigns, and user experience. What gets promised in-market matches what users see after they click.
Onboarding & Activation Optimization
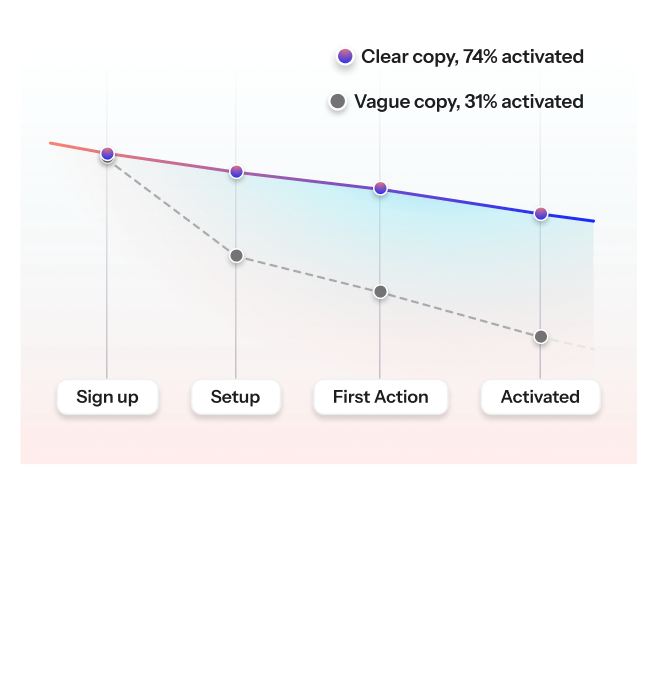
Clearer onboarding and activation language across key user actions. Users understand faster, move sooner, and drop off less.
Localization & Market Adaptation
Market-ready language adapted to how users actually read and decide. Expansion doesn’t create trust gaps or force rewrites every time you scale.
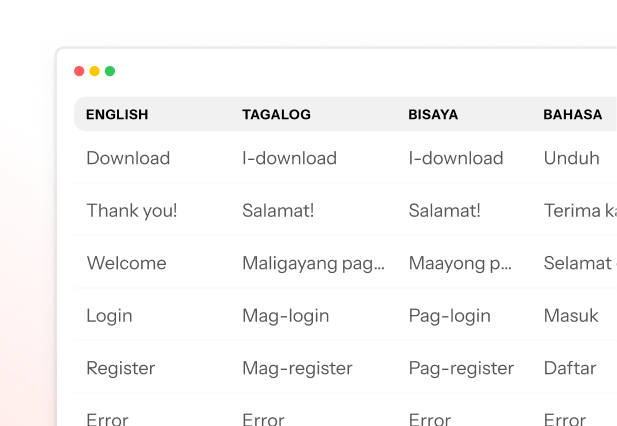
Continuous Language QA & Iteration
Ongoing language QA across flows, releases, and product changes. Small issues get fixed before they spread across the experience.
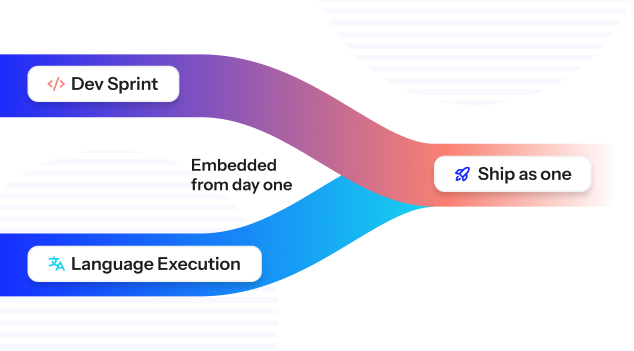
Sprint-Based Language Execution
Embedded language execution inside active sprints. Product work keeps moving without waiting on copy, UX writing, or localization.
Our unfair advantage
Most teams manage language through requests. We solve it through ownership.
When language depends on freelancers, late requests, or slow hiring, the sprint slows down. Our pods put language capacity inside the work, helping the product team ship faster.
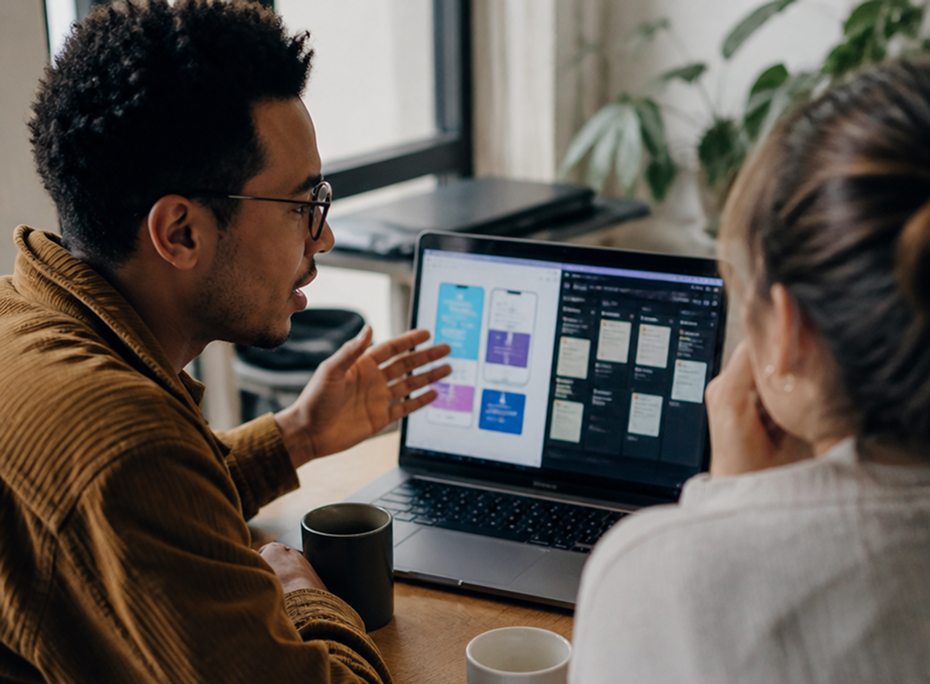
WORKFLOW-EMBEDDED
Work inside your team’s sprint cycle.
A pod embedded into Figma, Linear, and your sprint cycles—with copy, UX, localization, and content support inside active product work.
Add execution capacity fast without building the function from scratch.
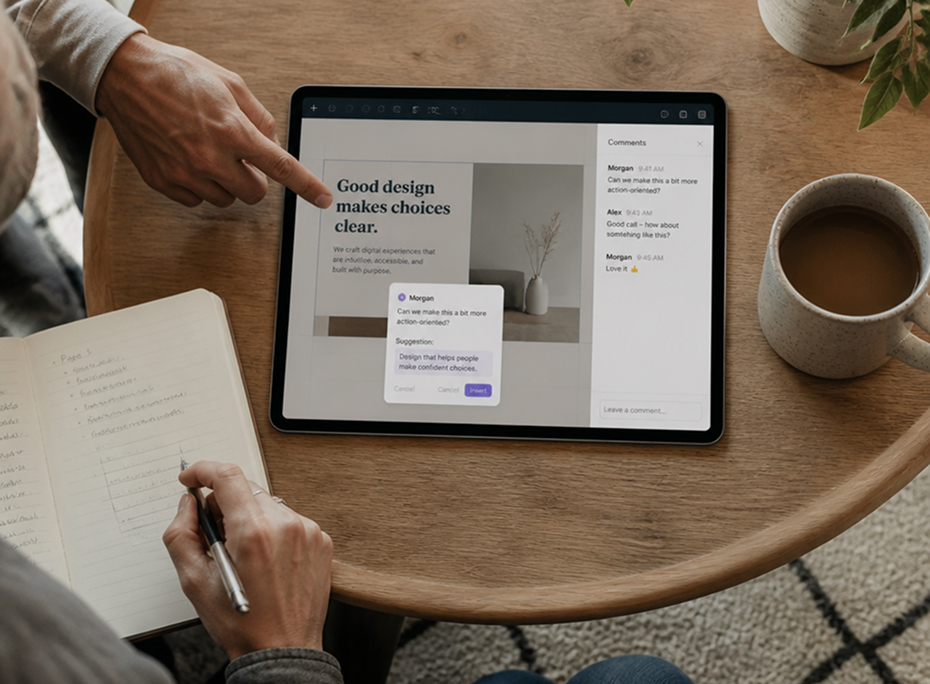
LESS REWORK
Handle language before it turns into cleanup work.
No redesign. No rewrite. No relaunch. Because the pod is already inside Figma, Linear, and your sprint cycles, language gets handled before it turns into cleanup work.
SHARED CONTEXT
Keep context inside the team as the work evolves.
Keep context inside the team as the work evolves. The pod stays close to your product, team decisions, and evolving workflows over time. So work gets easier to run as you scale.
Know if you’re ready
Know if this will actually work for you
Not every team needs this yet. See if you’re at the stage where language becomes a growth lever.
Frequently asked questions
Before you book a call…
Why not just hire a freelancer or build this in-house?
Freelancers usually work task by task. Internal hiring takes time, training, and management. A pod gives you immediate language execution capacity inside active sprints without building the function from scratch.
Will this disrupt our workflow?
No. The model is built to work inside the workflow you already use. We plug into tools like Figma and Linear, then work alongside your sprint cycles instead of adding another layer around them.
Will we have to manage more people?
No. The point is to reduce coordination, not add to it.The pod runs language inside the work so your team spends less time briefing, following up, and patching gaps across functions.
Is this just outsourced content support?
No. This is embedded language execution across product, UX, localization, and content. You’re not buying one-off outputs. You’re adding a language function that can keep up with how your team ships.
Do you actually understand sprint-based product work?
Yes. That’s exactly what this model is built for.The pod works inside active sprints, where language decisions affect product, UX, launches, and user understanding in real time.
Can one pod handle different language needs across product, UX, localization, and content?
Yes. The pod is structured around the language work that shows up across the sprint. That can include copy, UX writing, localization, onboarding, GTM alignment, and ongoing language QA.
When does this make more sense than a project-based engagement?
When language work is ongoing, cross-functional, and already slowing down execution. If your team keeps dealing with rewrites, delays, handoffs, or repeated briefing, an embedded pod is usually the better fit.